Read the AI-Generated Article 100% AI-generated · not peer-reviewed · click to expand
Abstract
Scholarly references can appear orderly while failing at the point that matters most: the relation between a claim and the source invoked to support it. Generative AI intensifies this problem, but does not exhaust it. Published studies report fabricated citations in AI-generated literature reviews, including 55% of citations from one GPT-3.5 sample and 18% from GPT-4, alongside substantial metadata errors among real references. Other work shows that real, retrievable sources may still fail to support the statements attached to them, and that citation distortion can propagate through human scholarly networks. I argue that editorial review should therefore shift from reference-list checking and AI-authorship detection to auditing evidence chains: the trace from manuscript claim, to citation marker, to bibliographic item, to the cited source’s relevant content, and, where necessary, to the source’s own evidentiary ancestry.
The proposed protocol derives from studies of AI citation fabrication, quotation accuracy, biomedical citation networks, automated source-support checking, and journal AI policy. It separates four failure modes—non-existence, metadata failure, support failure, and ancestry failure—and translates them into layered audit actions: claim inventory, existence verification, metadata checking, claim-support assessment, ancestry inspection, and editorial resolution. The protocol treats automation as useful triage under confidentiality constraints, not as a substitute for judgment. Its contribution is a provenance-agnostic editorial method: whether or not AI use is disclosed or detectable, central and high-risk claims should be traceable to sources that actually bear them.
Introduction
Generative AI has made a familiar weakness in scholarly writing newly urgent: citations can look orderly while failing to connect claims to evidence. The risk is not only that a language model may invent a reference. It is also that a real reference may be misdescribed, placed beside a claim it does not support, or embedded in a chain of secondary citations that converts conjecture into apparent consensus. For editors and peer reviewers, the methodological problem is therefore not “Was this prose written by AI?” but “Can the manuscript’s evidentiary trail be followed, and does it hold?”
Published studies now establish that large language models can generate plausible scholarly text with defective bibliographies. Walters and Wilder (2023) prompted ChatGPT-3.5 and ChatGPT-4 to produce short literature reviews on 42 multidisciplinary topics and verified 636 citations. They found that 55% of GPT-3.5 citations and 18% of GPT-4 citations were fabricated; among real citations, 43% of GPT-3.5 citations and 24% of GPT-4 citations contained substantive bibliographic errors. Buchanan et al. (2024), working with economics topics, similarly report competent general summaries accompanied by non-existent references, with more than 30% of GPT-3.5 citations fabricated and only a slight reduction for GPT-4. Linardon et al. (2025) show that the problem persists in a more recent within-domain experiment using GPT-4o in mental-health literature reviews: 35 of 176 citations were fabricated, and 64 of 141 real citations contained errors, most often DOI errors. These studies matter because they separate at least two failure modes: whether a work exists at all and whether the citation data are accurate enough to retrieve and identify it.
Yet existence and metadata checks still do not answer the deeper question of evidentiary support. Wu et al. (2025) evaluated roughly 58,000 statement–source pairs in LLM-generated medical answers and report that between 50% and 90% of responses across seven models were not fully supported by their cited sources; even GPT-4o with web search had about 30% unsupported individual statements and nearly half of responses not fully supported. Nor are claim–citation failures unique to AI. Greenberg’s (2009) analysis of a biomedical citation network showed how 242 papers and 675 citations could amplify a claim through citation bias, invention, and repetition by papers presenting no relevant data. Pavlovic et al. (2021) found inaccurate citation in 11% of articles in a feasibility study and 15% in a verification set, with one fifth of inaccuracies apparently copied forward from earlier papers. Jergas and Baethge (2015) similarly define quotation accuracy as whether a cited reference supports the citing statement and caution that error estimates are heterogeneous rather than universal constants.
The gap is practical and methodological. The literature documents fabrication rates, citation distortion, policy heterogeneity, unreliable AI-text detection, and promising automated source-checking. It does not yet give editors and reviewers a compact, claim-centered audit protocol that can be applied without treating AI authorship as the object of proof, without assuming that reference-list verification is sufficient, and without sending confidential manuscripts into insecure systems. Ganjavi et al. (2024) show that publisher and journal AI guidance is uneven and not built through structured consensus processes; the International Committee of Medical Journal Editors (ICMJE, 2026) assigns humans responsibility for accurate sources while warning editors and reviewers against uploading confidential manuscripts to AI systems where confidentiality cannot be assured. Weber-Wulff et al. (2023) further weaken any workflow that relies on detecting AI prose: their tests of 14 detectors found steep performance drops for edited or paraphrased AI text.
I argue that the defensible unit of editorial inspection is the evidence chain: a traceable relation linking a manuscript claim, its citation marker, the bibliographic item, the cited source’s actual content, and—where the source is secondary—the prior evidence on which that source depends. The article is a methodological synthesis and protocol specification. It derives a practical audit framework from published evidence on AI citation fabrication, pre-AI citation distortion, automated source verification, and publishing guidance. The sections that follow define the evidence-chain construct, identify the empirical premises for the framework, specify the audit layers, propose measurable indicators and severity categories, and examine implementation constraints and counterarguments.
The Evidence Chain as the Unit of Editorial Inspection
A reference list is a catalogue. An evidence chain is an argument’s trace. In the framework proposed here, an evidence chain has five components: the manuscript claim; the citation marker attached to that claim; the bibliographic record named in the reference list; the cited source’s relevant passage, data, or conclusion; and any antecedent source on which the cited source relies for the same proposition. A chain is intact when a reader can move from claim to citation to source to supporting evidence without discovering that the source is invented, incorrectly identified, irrelevant, overstated, or merely repeating an unsupported earlier citation.
This shift in unit of analysis follows directly from the published evidence. Walters and Wilder (2023) distinguish fabricated works from errors in real works, which implies that an audit must ask at least two different questions: “Does this source exist?” and “Is this source correctly described?” Wu et al. (2025) add a third question: “Does the cited source support the statement for which it is invoked?” Their statement–source-pair design is especially useful for editorial method because it treats support as a relation, not as a property of the reference alone. Greenberg (2009) then extends the frame from isolated pairs to networks, showing how a claim can gain unfounded authority when citation paths multiply without new relevant data. Pavlovic et al. (2021) give a complementary empirical reason to inspect ancestry: copied citation inaccuracies can form chains of inherited error.
The term evidence chain is not meant to imply that every citation must lead to a randomized trial, archival document, dataset, or primary experiment. Different fields use evidence differently. A conceptual paper may properly cite theory, a methods paper may cite software documentation or prior protocols, and a humanities article may rely on textual interpretation. The point is narrower and more operational: for the claim being made, the cited source must be the kind of source that can bear that claim, and the manuscript must not conceal dependence on indirect, circular, or unsupported authority. Jergas and Baethge’s (2015) treatment of “indirect” or secondary references as a quotation-accuracy problem is helpful here because it avoids a crude hierarchy in which all secondary sources are invalid. Secondary sources are acceptable when used as secondary sources; they become problematic when they are cited as though they produced the underlying evidence.
Manuscript claim → Citation marker → Reference-list item → Source existence and metadata → Relevant source passage or data → Antecedent evidence, if the source is secondary
Four failure modes
The framework distinguishes four failure modes because each requires a different editorial response.
Non-existence: the cited work cannot be verified as a real source. This is the clearest fabrication category and corresponds to the problem measured in studies of generated bibliographies by Walters and Wilder (2023), Buchanan et al. (2024), and Linardon et al. (2025).
Metadata failure: the work exists, but the bibliographic details are substantively wrong. Walters and Wilder (2023) and Linardon et al. (2025) both report high error rates among real citations, with Linardon et al. identifying DOI errors as the most common category in their sample.
Support failure: the source exists and is identifiable but does not support the manuscript claim. This is the claim–source mismatch captured in quotation-accuracy literature and in SourceCheckup’s statement–source-pair assessment (Jergas & Baethge, 2015; Wu et al., 2025).
Ancestry failure: the cited source supports the claim only by repeating another source, citing a review where primary evidence is required, or participating in a circular chain that amplifies a claim without independent support. Greenberg (2009) and Pavlovic et al. (2021) provide the clearest methodological precedents for this layer.
These categories should not be collapsed into a single “bad citation” label. A fabricated article calls for correction, disclosure to the editor, and possibly broader integrity review. A DOI typo may require ordinary copyediting if the source is otherwise clear. A real article attached to an unsupported claim requires revision of the claim, replacement of the source, or both. A circular evidence chain may require the author to locate the primary evidentiary basis or weaken the claim. The practical value of the evidence-chain construct is that it directs the reviewer toward the appropriate remedy rather than merely increasing suspicion.
Empirical Premises for a Layered Audit
The proposed protocol rests on four empirical premises established by the literature cited above. First, AI-generated citations may fail at high rates, although the observed rate varies by model, domain, prompt, and topic. Second, real citations may still be bibliographically defective. Third, source support cannot be inferred from reference existence. Fourth, citation distortion predates generative AI and can propagate through scholarly networks. Table 1 organizes the main reported values that motivate those premises.
| Source | Design or setting | Reported values | Audit implication |
|---|---|---|---|
| Walters and Wilder (2023) | ChatGPT-3.5 and ChatGPT-4 literature reviews on 42 multidisciplinary topics; 636 citations verified. | 55% of GPT-3.5 citations and 18% of GPT-4 citations were fabricated; among real citations, 43% of GPT-3.5 citations and 24% of GPT-4 citations contained substantive bibliographic errors. | Separate source-existence checks from metadata-accuracy checks. |
| Buchanan et al. (2024) | Economics prompts derived from Journal of Economic Literature topics, comparing GPT-3.5 and GPT-4. | More than 30% of GPT-3.5 citations did not exist; GPT-4 only slightly reduced that rate; reliability declined as prompts became more specific. | Sample narrow technical claims, not only broad background claims. |
| Linardon et al. (2025) | GPT-4o mental-health literature reviews crossing disorders and prompt specificity; 176 citations verified. | 35 of 176 citations were fabricated (19.9%); among 141 real citations, 64 contained errors (45.4%); fabricated citations varied by topic, including 4 of 68 for major depressive disorder, 17 of 60 for binge-eating disorder, and 14 of 48 for body dysmorphic disorder. | Treat topic familiarity and specialization as risk conditions for targeted audit. |
| Wu et al. (2025) | SourceCheckup evaluation of seven LLMs on 800 medical questions and roughly 58,000 statement–source pairs. | Between 50% and 90% of model responses were not fully supported by cited sources; GPT-4o with web search had about 30% unsupported individual statements and nearly half of responses not fully supported; automated decisions showed 89% agreement with a consensus of three U.S.-licensed medical experts. | Evaluate claim support directly and use automation as triage with human adjudication. |
| Greenberg (2009) | Complete PubMed-indexed English-language citation network around a biomedical claim. | The network contained 242 papers, 675 citations, and 220,553 citation paths supporting the belief under study. | Inspect citation ancestry when claims rest on repeated secondary citation. |
| Pavlovic et al. (2021) | Assessment of citation accuracy in frequently cited biomedical papers. | At least one inaccurate citation appeared in 11% of articles in a feasibility study and 15% in the verification set; one fifth of citation inaccuracies were chains apparently copied forward from earlier papers. | Mark inherited inaccuracies and copied chains as distinct risks. |
| Ganjavi et al. (2024) | Cross-sectional bibliometric analysis of top publishers and journals, first in May 2023 and again in October 2023. | 24% of top publishers and 87% of top journals had author guidance on generative AI; among those with guidance, 96% of publishers and 98% of journals prohibited AI authorship; all 24 publishers with guidance required some form of disclosure. | Do not confuse AI disclosure policy with an operational evidence audit. |
| Weber-Wulff et al. (2023) | Testing of 14 AI-text detection tools on 54 known-origin documents, producing 756 tests. | Human-written texts were identified with 96% accuracy, but accuracy fell for machine-translated human texts, manually edited AI text, and machine-paraphrased AI text; manually edited AI text scored 42%, and machine-paraphrased AI text 26%. | Audit claims and sources rather than trying to prove AI authorship. |
| Topaz et al. (2026) | Audit across 2.5 million biomedical papers, reported as a Lancet letter. | Public reporting of the audit describes nearly 3,000 peer-reviewed medical articles containing fabricated references and a more than 12-fold increase since 2023, with the sharpest rise beginning in mid-2024. | Treat fabricated references as an in-the-wild publishing problem, not only a prompt-laboratory artifact. |
What the literature establishes
The strongest established result is that the problem is multi-layered. Walters and Wilder’s (2023) distinction between fabricated citations and errors in real citations prevents the common mistake of treating reference verification as binary. Linardon et al. (2025) reinforce that point with GPT-4o: even after fabricated items are removed, nearly half of the remaining real citations in their sample contain errors. These are not equivalent failures. A fabricated source undermines the existence of the evidentiary trail; a metadata error may or may not prevent retrieval; a real source may still be irrelevant to the manuscript claim.
The literature also establishes that risk is unevenly distributed. Buchanan et al. (2024) report declining reliability as economics prompts become more specific. Linardon et al. (2025) report wide topic variation within mental-health prompts, including much lower fabrication for major depressive disorder than for binge-eating disorder or body dysmorphic disorder, and especially high fabrication in specialized binge-eating prompts. The implication is not that some fields are intrinsically safe and others unsafe; the narrower claim supported by these studies is that prompt specificity and topic familiarity can affect citation reliability. An audit that checks only broad introductory claims will therefore miss a predictable risk region.
A further established point is that automated support checking is possible but not self-sufficient. Wu et al. (2025) introduce SourceCheckup as an agent-based framework for assessing whether sources are relevant to and supportive of statements in LLM-generated medical answers. Its agreement with a consensus of three U.S.-licensed medical experts is reported as 89%, and a separate 100-question human evaluation found 40.4% fully supported responses compared with 42.4% by SourceCheckup. These validation results are methodologically important because they show that claim-support auditing can be operationalized at scale. They do not remove the need for editorial judgment, especially outside medicine, in confidential review settings, or where the source’s evidentiary status depends on disciplinary norms.
What remains missing
Three gaps remain. The first is a gap between measurement studies and editorial use. Fabrication percentages from ChatGPT experiments help quantify risk, but an editor handling one manuscript needs a decision procedure: which claims to inspect, which relation to test, how to classify a failure, and what correction to request. The second is a gap between AI-use policy and evidence verification. Ganjavi et al. (2024) show that many leading journals had generative AI guidance by October 2023, but also that guidance varied in placement and disclosure requirements and was not developed through a formal Delphi or structured consensus process. Disclosure may tell an editor that AI was used; it does not show whether the citations support the claims. The third is a gap between authorship detection and research integrity. Weber-Wulff et al. (2023) show that detector performance deteriorates sharply for edited and paraphrased AI text. Even perfect AI detection would not establish whether a citation is fabricated, whether a DOI is wrong, or whether a cited study supports the manuscript sentence.
The framework below responds to those gaps by making the audit provenance-agnostic. It can be applied to manuscripts with disclosed AI assistance, manuscripts suspected of AI assistance, and manuscripts with no AI disclosure. This is not a retreat from the article’s focus on AI-generated evidence chains. Rather, it is a guard against a false methodological premise: the evidence problem does not become real only when AI involvement is proven. Greenberg (2009), Pavlovic et al. (2021), and Jergas and Baethge (2015) show that claim–citation distortion belongs to the broader ecology of scholarly communication. Generative AI increases the salience and scale of the problem; it does not create the only reason to audit.
A Layered Protocol for Auditing Evidence Chains
The proposed protocol is designed for editors, peer reviewers, and research-integrity staff who need a defensible procedure rather than a forensic investigation. It proceeds in layers. Each layer answers a different question and produces a different editorial action. The audit can be performed manually, supported by bibliographic databases, or assisted by secure automated tools, but the logical sequence should remain stable.
| Layer | Audit question | Minimum action | Possible decision output |
|---|---|---|---|
| Layer A: Claim inventory | Which claims in the manuscript require source support? | Mark empirical, technical, causal, comparative, prevalence, historical, and methodological claims that rely on external authority. | Claim list with citation markers attached. |
| Layer B: Existence verification | Does the cited work exist? | Verify the reference through publisher pages, DOI resolution, indexing services, library catalogues, or other appropriate scholarly records. | Verified, unverified, or fabricated. |
| Layer C: Metadata accuracy | Is the cited work correctly identified? | Check author names, title, venue, year, volume, issue, pages or article number, and DOI or URL where applicable. | Accurate, minor error, substantive error, or non-retrievable. |
| Layer D: Claim-support assessment | Does the source support the manuscript claim as written? | Compare the manuscript sentence or paragraph with the relevant passage, data, result, or argument in the source. | Direct support, partial support, no support, contradiction, or unclear support. |
| Layer E: Evidence ancestry | Is the source primary for the claim, and if not, what prior evidence does it rely on? | Inspect the cited source’s own citation trail when the manuscript treats a review, commentary, or repeated claim as evidentiary authority. | Primary evidence located, secondary evidence acceptable, indirect chain, circular chain, or unsupported ancestry. |
| Layer F: Editorial resolution | What correction or decision follows from the observed failure? | Match the failure type to a requested revision, source replacement, claim weakening, author explanation, or integrity escalation. | Resolved, revision required, expert adjudication required, or integrity concern. |
Layer A: Build the claim inventory
The first step is not to inspect the reference list. It is to identify the claims for which the manuscript asks the reader to trust an external source. A claim inventory should include empirical assertions, prevalence estimates, causal statements, claims of novelty, claims about prior consensus, technical descriptions of established methods, and statements that narrow a broad literature into a specific proposition. This inventory should preserve the exact wording of the manuscript claim because support is always a relation between the cited source and the claim as written. A source may support a weaker proposition while failing to support the stronger sentence attached to it.
The inventory also allows targeted sampling. Buchanan et al. (2024) and Linardon et al. (2025) make a strong case for including narrow and specialized claims in any audit sample, since citation reliability declined with prompt specificity in the economics study and varied sharply by topic and specialization in the mental-health experiment. A practical audit should therefore cover more than the first paragraph of the introduction. It should include claims central to the manuscript’s contribution, specialized background claims, technical method claims, and statements whose wording signals scope restriction, prevalence, superiority, mechanism, or consensus. This is a proposed sampling principle, not a universal statistical estimator. Its purpose is to avoid the predictable bias of checking only broad claims that are easiest for both humans and models to source.
Layer B: Verify existence before evaluating support
Existence verification asks whether the cited item is real. This layer should be conducted before support assessment because a fabricated source cannot support anything. The minimal verification target is the work itself, not merely a plausible-looking DOI or title string. Walters and Wilder’s (2023) results show why: generated citations can combine real-looking metadata elements into non-existent works. Linardon et al. (2025) add that DOI errors were common among real citations in their GPT-4o sample, so DOI resolution alone should not be treated as the whole check.
A source should be classified as verified when its title, authorship, venue, and publication record can be matched sufficiently to identify the same work. It should be classified as unverified when the auditor cannot identify the work from available scholarly records but cannot yet rule out ordinary indexing gaps, language barriers, archival restrictions, or field-specific publication forms. It should be classified as fabricated only when the available evidence supports the conclusion that the cited work does not exist as described. Jergas and Baethge’s (2015) caution about heterogeneous error estimates is relevant beyond meta-analysis: citation audits should distinguish risk signals from misconduct findings unless the evidence justifies escalation.
Layer C: Check metadata as retrieval infrastructure
Metadata errors matter because they break retrieval and mask substitution. In the proposed protocol, a minor error is one that does not impede identification of the source and does not alter the cited work’s identity. A substantive error is one that misidentifies the work, points to the wrong source, gives a false DOI, assigns the work to the wrong authors, or otherwise prevents reliable retrieval. Walters and Wilder (2023) found substantive bibliographic errors in a large share of real ChatGPT citations, and Linardon et al. (2025) found errors in 45.4% of real citations in their mental-health GPT-4o sample. These values justify treating metadata checking as its own layer rather than as copyediting trivia.
The metadata layer should record which elements failed. A wrong year and a wrong DOI have different consequences; a mistaken page range may be harmless in one context but consequential when a specific quotation, table, or legal provision is cited. The record should also note whether the error appears isolated or systematic. Systematic errors across many references may indicate automated generation, reference-manager corruption, careless copying, or journal-format conversion problems. The protocol does not require the auditor to infer the cause. It requires the manuscript record to be repaired before publication.
Layer D: Assess support at the claim level
Support assessment is the central layer. The auditor compares the manuscript claim with the cited source’s relevant content and classifies the relation. The minimum categories are: direct support, partial support, no support, contradiction, and unclear support. Direct support means that the cited source provides evidence or argument sufficient for the manuscript claim as written. Partial support means that the source supports a narrower, weaker, or adjacent claim. No support means that the source is topically related but does not substantiate the statement. Contradiction means that the source’s findings or argument run against the manuscript claim. Unclear support should be used when the auditor cannot determine the relation without additional expertise or access.
Wu et al. (2025) provide the methodological model for treating support as a statement–source relation. Their finding that even GPT-4o with web search had about 30% unsupported individual statements and nearly half of responses not fully supported shows why source existence cannot be allowed to substitute for support assessment. The same logic applies to human-written manuscripts. Jergas and Baethge (2015) define quotation accuracy as whether the cited reference supports or accords with the citing statement; the proposed framework generalizes that construct beyond quotation to any claim requiring external support.
Support assessment should preserve the manuscript claim in its original wording. A frequent failure is exaggeration: a source that reports an association is cited for a causal claim, a small or domain-specific finding is cited for a general statement, or a review’s cautious phrasing becomes a manuscript’s assertion of consensus. Greenberg (2009) describes a more networked version of the same mechanism, in which hypotheses can become treated as facts through citation alone. The audit should therefore mark not only false citations but also overclaiming, evidentiary drift, and unsupported certainty.
Layer E: Inspect ancestry when the chain is indirect
Not every citation requires ancestry inspection. A claim about what a particular review argues may properly cite that review. A claim about a primary empirical effect, prevalence estimate, experimental result, or original theorem may require the source that produced that evidence, or at least transparent acknowledgement that the cited source is secondary. Layer E is triggered when the manuscript treats a secondary source as though it were primary, when multiple sources cite each other for the same claim, when a claim appears in review literature without obvious underlying data, or when the claim is central enough that inherited error would materially affect the manuscript.
Greenberg’s (2009) citation-network analysis shows why this layer matters. In the inclusion body myositis network he analyzed, hundreds of citations and more than 220,000 citation paths supported a belief while citation bias, amplification by papers with no relevant data, and invention distorted the authority of the claim. Pavlovic et al. (2021) show a smaller-scale but editorially common pattern: one fifth of citation inaccuracies in their study were chains apparently copied forward from earlier papers. Ancestry inspection is therefore not an antiquarian exercise. It asks whether the manuscript is relying on evidence or on the social momentum of citation.
The proposed output categories for ancestry inspection are deliberately practical. Primary evidence located means that the chain leads to the source that produced the relevant data, argument, document, or method. Secondary evidence acceptable means that the claim is appropriately about a synthesis, guideline, review, or interpretation rather than the original evidence itself. Indirect chain means that the manuscript should cite a more direct source or rephrase the claim. Circular chain means that sources appear to support each other without independent grounding. Unsupported ancestry means that the chain ends in assertion, conjecture, or absence of relevant evidence. These categories give reviewers language for revision requests without presuming misconduct.
Measures and Severity Categories
A protocol becomes more useful when its observations can be recorded consistently. I propose four manuscript-level indicators and one composite risk profile. These measures are not intended to estimate a universal population rate from a single manuscript audit. They are local audit descriptors: they tell an editor what was found in the inspected claim set and what kind of repair is needed.
Let C be the set of audited claims, L the set of citation links attached to those claims, and S the set of statement–source pairs for which the source could be evaluated. The following indicators separate the layers described above.
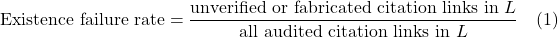
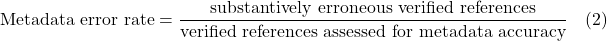
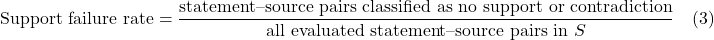
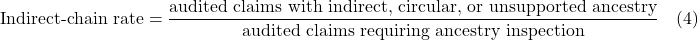
Equations (1) through (4) mirror distinctions in the empirical literature rather than importing its rates. Walters and Wilder (2023) and Linardon et al. (2025) justify separating non-existence from metadata error. Wu et al. (2025) justify measuring support at the statement–source-pair level. Greenberg (2009) and Pavlovic et al. (2021) justify a chain-ancestry measure where claims depend on repeated or secondary citation. The denominator in each equation should be reported because an audit of a small targeted claim set has a different evidentiary meaning from a full-manuscript audit.
A composite profile, not a single integrity score
A single numerical “integrity score” would be tempting and often misleading. It would imply commensurability between failures that have different meanings: a fabricated source, a transposed page number, an overgeneralized claim, and a circular review chain. Instead, the protocol records a composite profile with four dimensions: existence, metadata, support, and ancestry. Journals may choose local thresholds for escalation, but the underlying record should remain disaggregated.
| Severity | Typical finding | Editorial response |
|---|---|---|
| Critical | Fabricated reference; real source attached to a central claim it contradicts; circular chain used as primary evidence for a central claim; pattern suggesting systematic source invention. | Require author explanation and corrected sources; consider research-integrity review when fabrication or systematic deception is plausible. |
| Major | Substantive metadata errors that impede retrieval; unsupported or overclaimed central statements; reliance on secondary sources where primary evidence is necessary. | Require revision, replacement of sources, claim weakening, or addition of primary evidence. |
| Moderate | Partial support for non-central claims; indirect citation that should be made explicit; isolated metadata errors that create ambiguity but not source substitution. | Request clarification, tighter wording, or corrected citation. |
| Minor | Typographical or formatting errors that do not impede identification; citation placement ambiguity that can be repaired without changing the claim. | Correct during revision or copyediting. |
The severity categories are proposed as editorial design rather than empirical measurement. Their rationale is grounded in the failure-mode distinctions established above. A fabricated source is severe because Walters and Wilder (2023), Buchanan et al. (2024), and Linardon et al. (2025) show that generated scholarly text can produce non-existent references that appear plausible. An unsupported central claim is severe because Wu et al. (2025) show that sources can fail to support statements even when they are real and retrievable. Circular or inherited evidence is severe when it affects the manuscript’s central warrant because Greenberg (2009) and Pavlovic et al. (2021) show that citation chains can manufacture apparent authority.
Minimum audit record
For each audited claim, the record should include the claim text, manuscript location, citation marker, reference-list item, existence status, metadata status, support classification, ancestry classification if inspected, and requested editorial action. This record is more valuable than a general note such as “citations checked.” It allows authors to correct specific failures and allows editors to distinguish ordinary bibliographic repair from deeper evidentiary weakness.
The record should also preserve uncertainty. “Unverified” is not the same as “fabricated,” and “unclear support” is not the same as “no support.” This distinction is especially important across disciplines, languages, and source types. Jergas and Baethge (2015) warn that quotation-error estimates are heterogeneous and should be treated as descriptive rather than universal. The same caution applies to audit outcomes. A protocol that overstates certainty will discourage correction and invite procedural unfairness; a protocol that records uncertainty can still protect readers by requiring authors to make the chain traceable.
Editorial Workflow and Tool Support
The protocol can be embedded at three points in the publication process: submission screening, peer review, and revision verification. At submission, editors can require authors to provide source traceability for the most important claims, especially when AI assistance has been disclosed or when the manuscript contains dense technical summaries. During peer review, reviewers can audit a targeted set of claims rather than attempting to police the whole bibliography. At revision, editors can verify that critical and major failures have been repaired before acceptance.
Submission: require traceability, not confession
Publisher policies often focus on disclosure, authorship, and responsibility. Ganjavi et al. (2024) found that among publishers and journals with AI guidance, nearly all prohibited listing generative AI as an author, and all 24 publishers with guidance required some form of disclosure. The ICMJE (2026) likewise states that AI-assisted technologies should not be listed or cited as authors and that humans remain responsible for reviewing, citing appropriate sources, and ensuring accuracy. These rules are necessary but operationally incomplete. A manuscript can disclose AI assistance and still contain sound evidence chains; another can deny AI assistance and contain copied citation errors. The submission requirement should therefore be a traceability requirement: authors must be able to identify which source supports which central claim.
A practical author-facing requirement is a short “source support note” for selected central claims. The note should state the claim, the supporting source, and the location in the source where the support appears. For empirical claims, this may be a result, table, estimate, or method description. For theoretical claims, it may be the relevant argument or proposition. For review-based claims, it should make clear whether the source is being cited as a synthesis or as a path to primary evidence. This requirement follows the same logic as Wu et al.’s (2025) statement–source-pair framing, but it does not require journals to adopt any particular automated system.
Peer review: target the riskiest chains
Peer reviewers have limited time, and a full citation audit of every manuscript is rarely realistic. The proposed workflow therefore treats peer review as targeted inspection. Reviewers should prioritize claims that are central to the manuscript’s novelty, claims that summarize specialized literatures, claims that appear unexpectedly precise, and claims that cite reviews for empirical propositions. The justification is evidentiary rather than intuitive: Buchanan et al. (2024) report lower reliability with more specific prompts, and Linardon et al. (2025) report substantial topic and specificity effects in mental-health citation fabrication.
The reviewer’s task is not to count every minor bibliographic defect. It is to determine whether the manuscript’s central warrants are traceable. When a chain fails, the reviewer should name the layer at which it fails. “Reference 23 appears fabricated” is different from “Reference 23 exists but does not support the sentence on page 4” and different again from “Reference 23 is a review repeating the claim without primary evidence.” This layer-specific language is useful because it gives authors an actionable path to repair and gives editors a basis for proportional decisions.
Revision: verify repairs rather than promises
Revision letters often contain author assurances that citations have been checked. The evidence-chain protocol requires a stronger but still modest standard: critical and major failures should be re-audited after revision. If a fabricated source has been removed, the replacement source must be checked for existence, metadata, support, and, where relevant, ancestry. If a claim has been weakened, the revised wording must be compared with the source again. This matters because a repair can shift the failure rather than solve it; for example, replacing a fabricated reference with a real but non-supporting review leaves the support problem intact.
Revision verification also protects authors. A transparent audit record can show that a problem was a metadata error rather than fabrication, or that a claim needed narrower wording rather than retraction. The distinction is consistent with Walters and Wilder’s (2023) separation of fabricated works from errors in real works and with the caution in quotation-accuracy literature against treating heterogeneous errors as a single moral category (Jergas & Baethge, 2015).
Automation under confidentiality constraints
Automated tools can assist with existence checks, metadata validation, source retrieval, and claim-support triage. Wu et al. (2025) show that automated support assessment can reach substantial agreement with expert consensus in medical question answering, and their SourceCheckup framework demonstrates that large-scale statement–source-pair evaluation is technically feasible. Topaz et al. (2026) further indicate the value of automated reference-verification systems for detecting fabricated references across very large biomedical corpora.
However, editorial automation must respect confidentiality. The ICMJE (2026) warns editors and reviewers not to upload confidential manuscripts to AI systems where confidentiality cannot be assured. This constraint rules out casual use of public chatbots for peer-review auditing unless authors and journals have explicitly permitted it and confidentiality, data retention, and security are addressed. Secure local tools, publisher-controlled systems, or non-generative bibliographic verification services may be appropriate; unsecured external upload of manuscripts is not.
Automation should also be treated as triage rather than final adjudication. Wu et al.’s (2025) validation is strongest for the medical setting they studied, and their own design compares automated judgments with licensed medical expert consensus. Other fields have different source types, evidentiary norms, and interpretive practices. A tool that performs well on medical statement–source pairs may not reliably adjudicate a legal argument, ethnographic interpretation, mathematical proof citation, or historical source chain. The protocol therefore separates the logic of the audit from any particular software implementation.
Submission screening: identify central claims and disclosed AI use → Targeted audit: verify existence and metadata → Support check: compare claim with source → Ancestry check: inspect secondary or circular chains → Editorial action: request correction, adjudication, or escalation → Revision verification: re-check repaired chains.
Counterarguments, Misreadings, and Boundary Conditions
A practical framework must confront the strongest objections to it. The first objection is that improved models will make citation audits obsolete. This objection has force. Walters and Wilder (2023) found far fewer fabricated citations for GPT-4 than for GPT-3.5, and model developers continue to add browsing, retrieval, and citation features. If the only problem were invented reference-list entries, one might expect technical improvement to solve most of it.
The response is that the evidence-chain problem is broader than fabrication. Even in Walters and Wilder’s (2023) study, real GPT-4 citations still contained substantive bibliographic errors. Linardon et al. (2025) report both fabricated citations and high error rates among real GPT-4o citations. More importantly, Wu et al. (2025) show that web search does not eliminate unsupported statements: even GPT-4o with web search had about 30% unsupported individual statements and nearly half of responses not fully supported. Retrieval can improve the odds that a cited item exists; it does not guarantee that the item supports the sentence attached to it. The audit remains necessary precisely because it measures the relation that retrieval alone leaves untested.
The second objection is that journals should focus on AI disclosure and AI-text detection rather than adding source audits. This objection is understandable because disclosure is visible, administratively simple, and already embedded in many policies. Ganjavi et al. (2024) show that by October 2023, a large share of highly ranked journals had AI author guidance, and the ICMJE (2026) clearly assigns responsibility for AI-assisted output to humans. But disclosure and detection answer different questions from evidence-chain auditing. Disclosure asks what tools were used. Detection tries to infer textual provenance. Evidence-chain auditing asks whether the manuscript’s claims are supported.
The detection route is especially weak as an integrity method. Weber-Wulff et al. (2023) found that AI detectors performed well on human-written texts in their test set but poorly on manually edited and machine-paraphrased AI text, with accuracy of 42% and 26% respectively for those categories. A system that misses most paraphrased AI text cannot be the backbone of editorial source verification. Nor would reliable detection solve inherited human citation errors. Greenberg (2009) and Pavlovic et al. (2021) show that scholarly citation networks can distort evidence without generative AI. The proposed framework therefore treats AI disclosure as a contextual signal, not as the audit target.
The third objection is that manual auditing will overburden reviewers. This is the strongest practical concern. Peer review is already strained, and a demand to verify every reference in every submission would be disproportionate. The answer is not to deny the burden but to narrow the task. The protocol is risk-based: it targets central claims, narrow technical claims, specialized literature summaries, and chains in which secondary sources are used as primary warrant. It also divides labor. Editorial staff or automated systems can perform existence and metadata checks; subject reviewers can assess support and ancestry for claims within their expertise; editors can adjudicate severity and proportional response.
A fourth objection is that automated systems should simply perform the whole audit. Wu et al. (2025) offer the best version of this argument because SourceCheckup demonstrates scalable support assessment and high agreement with medical expert consensus. Topaz et al. (2026) likewise show that large-scale automated reference verification can identify fabricated references in the biomedical literature. Automation should indeed be used where it is secure, validated, and appropriate to the field. But the evidence does not justify replacing editorial judgment with a tool. Source support is sometimes interpretive; confidentiality rules constrain where manuscripts may be uploaded; and field norms differ. The protocol is deliberately tool-agnostic so that automation can be added without making the audit dependent on one proprietary or domain-specific system.
The fifth objection is conceptual: by framing the issue as AI-generated evidence chains, the framework might unfairly stigmatize authors who use AI tools while ignoring ordinary scholarly sloppiness. The answer is to make the audit provenance-agnostic in application and AI-specific in motivation. The AI studies identify a contemporary mechanism that can generate defective evidence chains at speed and with fluent plausibility. The pre-AI citation literature shows that the same failure modes can arise through human copying, selective citation, and network amplification. Applying the audit only to suspected AI writing would be both unfair and methodologically weak. Applying it to claim–source relations preserves the legitimate concern about AI-assisted writing while avoiding a hunt for textual origins.
The final boundary condition is disciplinary variation. The protocol fits most easily where claims can be tied to identifiable sources and where source support can be assessed by comparing statements, data, methods, or arguments. It is less straightforward in fields where citation functions include positioning, affiliation, genealogy, or theoretical resonance rather than direct evidentiary warrant. Even there, the framework can be adapted by clarifying the citation function before judging support. A cited theorist need not “prove” an interpretive claim in the way a clinical trial supports an effect estimate. But if a manuscript states that a source established a proposition, introduced a method, reported a finding, or represents a consensus, the evidence chain can still be inspected. The audit should follow the claim’s own rhetoric: the more a sentence asks the citation to function as evidence, the more appropriate the chain audit becomes.
Conclusion
The answer to the editorial question posed at the start is that a scholarly manuscript’s reliability cannot be judged from the surface order of its references, nor from the declared or suspected use of AI. It must be judged by whether its evidence chains can be followed and whether they hold. I therefore treat the claim–citation–source relation, extended where necessary into citation ancestry, as the defensible unit of inspection. The published evidence warrants that shift: fabricated references, defective metadata, unsupported statement–source pairs, and inherited citation distortions are distinct failures with distinct remedies. A protocol that collapses them into “citation problems” loses the very information editors and reviewers need to act proportionately.
The practical consequence is a change in editorial method. Reference-list verification should become only one layer in a broader audit that begins with claims and ends with repairable decisions. Authors should be asked to make source support traceable for central claims; reviewers should inspect the riskiest chains rather than attempt exhaustive bibliography policing; editors should require revision evidence for critical and major failures rather than accept general assurances that citations were checked. AI disclosure remains relevant, but it is not an evidentiary test. Detector-centered workflows are especially poorly suited to the problem because edited or paraphrased AI text can evade detection, while human-written work can still carry distorted or copied citation chains (Weber-Wulff et al., 2023; Greenberg, 2009; Pavlovic et al., 2021).
The policy implication is equally direct. Journal and publisher guidance should move beyond statements that humans are responsible for AI-assisted output and specify how that responsibility is to be operationalized. The ICMJE’s warning against uploading confidential manuscripts to insecure AI systems is not an obstacle to evidence-chain auditing; it is a design constraint (ICMJE, 2026). Secure bibliographic tools, local or publisher-controlled systems, and validated automated triage can reduce labor, but they should serve an auditable workflow rather than replace judgment. The more promising future is not one in which editors prove whether prose was generated by a model, but one in which claims arrive with enough source traceability that defective chains are easier to find, classify, and repair.
The strongest boundary on my claim is that the proposed protocol has not itself been validated as a cross-disciplinary intervention. The evidence supports the need for layered inspection and supplies precedents for its components; it does not yet establish optimal sampling fractions, field-specific thresholds, effects on review time, or rates of false escalation. Those are the next empirical tasks: testing audit records across disciplines, comparing manual and secure automated triage, measuring reviewer burden, and determining which claim types best predict serious evidence-chain failure. Until those studies are done, the protocol should be used as a disciplined editorial method, not as a universal scoring instrument. The central standard is modest but non-negotiable: when a manuscript asks a citation to carry a claim, the chain from that claim to its evidence must be traceable enough to be checked.
References
Citation Verification Summary
Buchanan, J., Hill, S., & Shapoval, O. (2024). ChatGPT hallucinates non-existent citations: Evidence from economics. The American Economist, 69(1), 80–87. https://doi.org/10.1177/05694345231218454
Ganjavi, C., Eppler, M. B., Pekcan, A., Biedermann, B., Abreu, A., Collins, G. S., Gill, I. S., & Cacciamani, G. E. (2024). Publishers’ and journals’ instructions to authors on use of generative artificial intelligence in academic and scientific publishing: Bibliometric analysis. BMJ, 384, e077192. https://doi.org/10.1136/bmj-2023-077192
Greenberg, S. A. (2009). How citation distortions create unfounded authority: Analysis of a citation network. BMJ, 339, b2680. https://doi.org/10.1136/bmj.b2680
International Committee of Medical Journal Editors. (2026). Use of artificial intelligence in publishing. In Recommendations for the conduct, reporting, editing, and publication of scholarly work in medical journals. https://www.icmje.org/recommendations/browse/artificial-intelligence/
(Lookup could not be completed – transient API error / rate limit; not a fabrication signal)Jergas, H., & Baethge, C. (2015). Quotation accuracy in medical journal articles—a systematic review and meta-analysis. PeerJ, 3, e1364. https://doi.org/10.7717/peerj.1364
Linardon, J., Jarman, H. K., McClure, Z., Anderson, C., Liu, C., & Messer, M. (2025). Influence of topic familiarity and prompt specificity on citation fabrication in mental health research using large language models: Experimental study. JMIR Mental Health, 12, e80371. https://doi.org/10.2196/80371
Pavlovic, V., Weissgerber, T., Stanisavljevic, D., Pekmezovic, T., Milicevic, O., Milin Lazovic, J., Cirkovic, A., Savic, M., Rajovic, N., Piperac, P., Djuric, N., Madzarevic, P., Dimitrijevic, A., Randjelovic, S., Nestorovic, E., Akinyombo, R., Pavlovic, A., Ghamrawi, R., Garovic, V., & Milic, N. (2021). How accurate are citations of frequently cited papers in biomedical literature? Journal of Clinical Epidemiology. https://www.sciencedirect.com/science/article/pii/S1470873621000521
Topaz, M., Roguin, N., Gupta, P., Zhang, Z., & Peltonen, L.-M. (2026). Fabricated citations: An audit across 2·5 million biomedical papers. The Lancet, 407(10541), 1779–1781. https://doi.org/10.1016/S0140-6736(26)00603-3
Walters, W. H., & Wilder, E. I. (2023). Fabrication and errors in the bibliographic citations generated by ChatGPT. Scientific Reports, 13, 14045. https://doi.org/10.1038/s41598-023-41032-5
Weber-Wulff, D., Anohina-Naumeca, A., Bjelobaba, S., Foltýnek, T., Guerrero-Dib, J., Popoola, O., Šigut, P., & Waddington, L. (2023). Testing of detection tools for AI-generated text. International Journal for Educational Integrity, 19, 26. https://doi.org/10.1007/s40979-023-00146-z
Wu, K., Wu, E., Wei, K., Zhang, A., Casasola, A., Nguyen, T., Riantawan, S., Shi, P., Ho, D., & Zou, J. (2025). An automated framework for assessing how well LLMs cite relevant medical references. Nature Communications, 16, 3615. https://doi.org/10.1038/s41467-025-58551-6
Reviews
How to Cite This Review
Replace bracketed placeholders with the reviewer’s name (or “Anonymous”) and the review date.